Apache Cassandra Performance Tuning: Data Modeling, Secondary Indexes, and Compaction Strategies
Hello DevOps Engineers, DevSecOps Professionals, SREs, Platform Engineers, and Database Enthusiasts!
This week I spent time exploring one of the most popular distributed NoSQL databases—Apache Cassandra. During my hands-on experimentation, I focused on an area that often separates successful Cassandra deployments from struggling ones: performance optimization.
Many engineers install Cassandra successfully, but achieving optimal performance requires understanding:
- Data modeling principles
- Partition key design
- Secondary indexes
- Compaction strategies
- Read and write optimization
In this article, we'll continue from our previous Cassandra installation guide and explore practical techniques to improve query performance and design scalable Cassandra databases.
What We'll Learn
By the end of this article, you'll understand:
- How Cassandra data modeling differs from relational databases
- Why partition keys matter
- When to use (and avoid) secondary indexes
- How Cassandra compaction works
- Choosing the right compaction strategy for your workload
- Real-world use cases for STCS, LCS, TWCS, and UCS
Why Cassandra Performance Tuning Matters
A common mistake among engineers new to Cassandra is designing tables the same way they would in MySQL, PostgreSQL, or Oracle.
In traditional relational databases:
 |
| RDBMS vs Cassandra |
Cassandra is a query-driven database.
Your schema should be designed around how data will be queried, not merely how it will be stored.
Poor partition key design can result in:
- Full table scans
- Slow queries
- Uneven data distribution
- Hot partitions
- Increased latency
Lab 1: Optimizing Cassandra Data Modeling
Example of an Inefficient Data Model
Let's begin with a simple employee table:
CREATE KEYSPACE company_db
WITH replication = {'class': 'SimpleStrategy', 'replication_factor': 1};
USE company_db;

CREATE TABLE company_db.employees_bad (
id UUID PRIMARY KEY,
name TEXT,
department TEXT,
age INT,
city TEXT
);
Now let's Insert some sample records into the table and try to query it.
INSERT INTO employees_bad (id, name, department, age, city) VALUES (uuid(), 'Reemi', 'Engineering', 30, 'New York');
INSERT INTO employees_bad (id, name, department, age, city) VALUES (uuid(), 'Ausula Santhosh', 'Marketing', 40, 'San Francisco');
INSERT INTO employees_bad (id, name, department, age, city) VALUES (uuid(), 'Telluri Raja', 'Marketing', 40, 'San Francisco');
INSERT INTO employees_bad (id, name, department, age, city) VALUES (uuid(), 'Abdul Pathan', 'Marketing', 40, 'San Francisco');
Run the following queries and observe the issue
department is not part of the primary key.Improved Data Model
Instead, redesign the table based on the query pattern:
CREATE TABLE company_db.emp (
  id UUID,
  name TEXT,
  department TEXT,
  age INT,
  city TEXT,
  PRIMARY KEY(department,id)
);
Here:
departmentbecomes the partition keyidbecomes the clustering column
This allows Cassandra to directly locate the correct partition and retrieve data efficiently.
Rerun the Insert sample recordsINSERT INTO emp (id, name, department, age, city) VALUES (uuid(), 'Reemi', 'Engineering', 30, 'New York'); INSERT INTO emp (id, name, department, age, city) VALUES (uuid(), 'Ausula Santhosh', 'Marketing', 40, 'San Francisco'); INSERT INTO emp (id, name, department, age, city) VALUES (uuid(), 'Telluri Raja', 'Marketing', 40, 'San Francisco'); INSERT INTO emp (id, name, department, age, city) VALUES (uuid(), 'Abdul Pathan', 'Marketing', 40, 'San Francisco');Run queries and observe performance
SELECT * FROM emp;
SELECT * FROM emp WHERE department = 'Engineering';

Key Learning
Always ask:
"How will my application query this data?"
before designing a Cassandra table.
Unlike relational databases, Cassandra tables should be designed around access patterns.
Lab 2: Using Secondary Indexes Efficiently
Objective: Understand when secondary indexes are appropriate and when alternative modeling approaches are better.The Challenge
CREATE TABLE company_db.products (
id UUID PRIMARY KEY,
name TEXT,
category TEXT,
price DECIMAL
);

INSERT INTO products (id, name, category, price)
VALUES (uuid(), 'Laptop', 'Electronics', 120000.00);
INSERT INTO products (id, name, category, price)
VALUES (uuid(), 'Wireless Mouse', 'Electronics', 200.00);
INSERT INTO products (id, name, category, price)
VALUES (uuid(), 'Chair', 'Furniture', 150.00);
INSERT INTO products (id, name, category, price)
VALUES (uuid(), 'ErgoChair', 'Furniture', 1500.00);
INSERT INTO products (id, name, category, price)
VALUES (uuid(), 'ErgoStandSitTable', 'Furniture', 24050.00);

SELECT * FROM products ;
SELECT * FROM products WHERE category = 'Electronics';
will not work efficiently because
category is not part of the primary key.CREATE INDEX category_index ON products (category); SELECT * FROM products WHERE category = 'Electronics';

Secondary Index Best Practices
Use indexes when:
- Cardinality is moderate
- Query volume is low
- Dataset size is manageable
Avoid indexes when:
- Tables contain millions of rows
- High write throughput exists
- Query patterns are predictable
In production environments, a better approach is often designing a dedicated query table instead of relying heavily on secondary indexes.
Lab 3: Understanding Cassandra Compaction Strategies
Objective: Understand how different compaction strategies affect performance.Why Compaction Matters
Cassandra stores data in immutable SSTables. As writes occur, new SSTables are created. Without compaction:
 |
| Before compaction impact on SSTables |
Compaction merges SSTables to improve performance and reclaim storage.
We have 4 different options we have let's explore on each of these options in detail here. You can use `DESC TABLE emp`, This way we can check the current compaction strategy:

1. SizeTieredCompactionStrategy (STCS)
Scenario: An IoT application with a high volume of incoming sensor data.Use Case: An IoT platform collects data from thousands of sensors distributed across a smart city. Each sensor sends data continuously, leading to a high volume of writes.
Advantage: STCS is ideal for this write-heavy workload because it efficiently handles large volumes of data by merging smaller SSTables into larger ones, reducing write amplification and managing disk space effectively.
CREATE KEYSPACE iot
WITH replication = {'class': 'SimpleStrategy', 'replication_factor': 1};

use iot;

CREATE TABLE iot.sensor_data (
  sensor_id int,
  timestamp timestamp,
  data blob,
  PRIMARY KEY (sensor_id, timestamp)
) WITH compaction = {
  'class': 'SizeTieredCompactionStrategy',
  'min_threshold': 4,
  'max_threshold': 32
};

DESC TABLE  iot.sensor_data

Best For: Write-heavy workloads
Example Use Case
IoT sensor platforms generating continuous streams of telemetry data.
Advantages
- Optimized for high write throughput
- Lower write amplification
- Efficient disk usage
Typical Workloads
- IoT Platforms
- Log Aggregation Systems
- Event Streaming Pipelines
2. LeveledCompactionStrategy (LCS)
Best For Read-heavy workloads
Example Use Case
Social media platforms where users frequently access profiles, posts, comments, and likes.
Advantages
- Lower read latency
- Predictable performance
- Reduced SSTable scanning
Typical Workloads
- Social Networks
- Customer Portals
- Product Catalogs
CREATE KEYSPACE socialmedia
WITH replication = {'class': 'SimpleStrategy', 'replication_factor': 1};

USE socialmedia;

CREATE TABLE socialmedia.user_posts (
  user_id int,
  post_id int,
  content text,
  PRIMARY KEY (user_id, post_id)
) WITH compaction = {
  'class': 'LeveledCompactionStrategy',
  'sstable_size_in_mb': 160
};

DESC TABLE socialmedia.user_posts

3. TimeWindowCompactionStrategy (TWCS)
Best For Time-series databases
Example Use Case
Monitoring platforms collecting:
- CPU metrics
- Memory utilization
- Network traffic
- Application performance statistics
at regular intervals.
Advantages
- Optimized retention management
- Faster expiration of old data
- Reduced compaction overhead
Typical Workloads
- Prometheus-style Metrics
- Observability Platforms
- Log Analytics
CREATE KEYSPACE monitoring
WITH replication = {'class': 'SimpleStrategy', 'replication_factor': 1};

USE monitoring;

CREATE TABLE monitoring.server_metrics (
  server_id int,
  metric timestamp,
  cpu_usage double,
  memory_usage double,
  network_traffic double,
  PRIMARY KEY (server_id, metric)
) WITH compaction = {
  'class': 'TimeWindowCompactionStrategy',
  'compaction_window_unit': 'HOURS',
  'compaction_window_size': 1
};

DESC TABLE monitoring.server_metrics

4. UnifiedCompactionStrategy (UCS)
Best For Mixed read/write workloads
Example Use Case
E-commerce systems managing:
- Product updates
- User reviews
- Order processing
- Inventory tracking
simultaneously.
Advantages
- Adaptive behavior
- Balanced read/write performance
- Simplified tuning
Typical Workloads
- E-commerce Platforms
- SaaS Applications
- Multi-purpose Databases
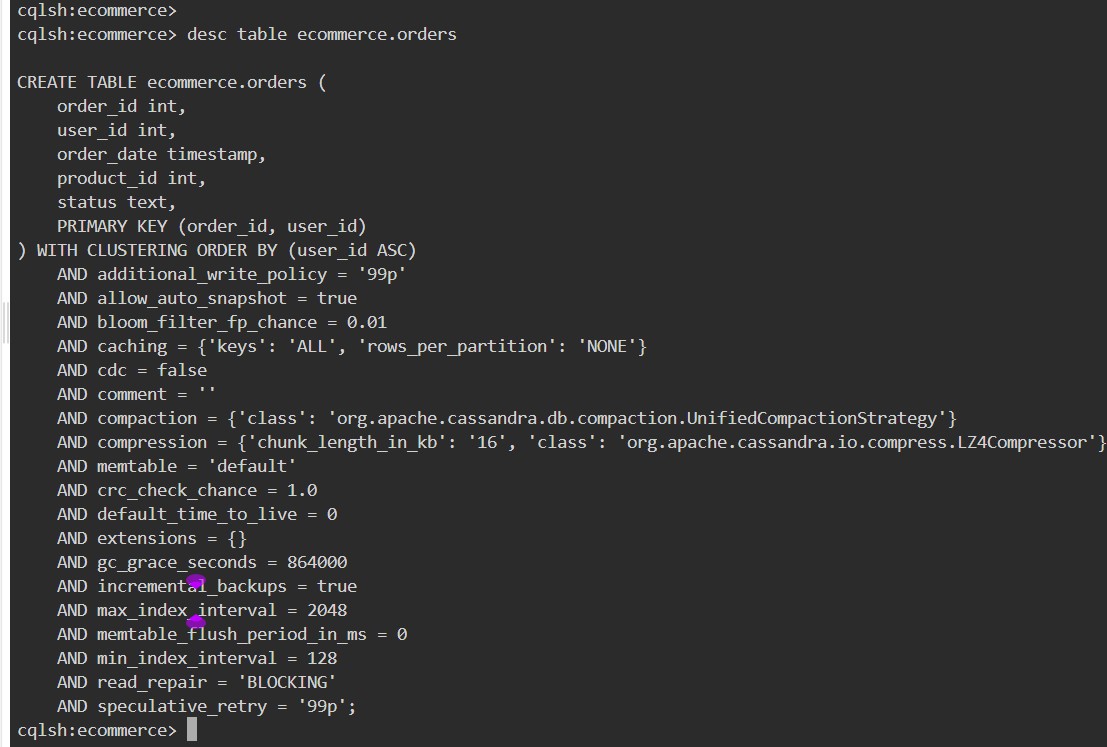
CREATE KEYSPACE ecommerce
WITH replication = {'class': 'SimpleStrategy', 'replication_factor': 1};

USE ecommerce;

CREATE TABLE ecommerce.orders (
  order_id int,
  user_id int,
  product_id int,
  order_date timestamp,
  status text,
  PRIMARY KEY (order_id, user_id)
) WITH compaction = {
  'class': 'UnifiedCompactionStrategy'
};

desc table ecommerce.orders
Choosing the Right Compaction Strategy
| Workload Type | Recommended Strategy |
|---|---|
| Heavy Writes | STCS |
| Heavy Reads | LCS |
| Time-Series Data | TWCS |
| Mixed Workloads | UCS |
Reader Challenge
Now it's your turn!
Challenge 1
Create a table for an Employee Attendance System and optimize it for:
Find attendance records by department
Find attendance records by date
Find attendance records by employee
Which partition key would you choose?
Challenge 2
Create two versions of a product table:
- Without an index
- With a secondary index
Compare query performance using:
TRACING ON;and observe the differences.
Challenge 3
Identify which compaction strategy would be most suitable for:
- Prometheus Metrics Storage
- Online Banking Platform
- Social Media Feed
- Smart City IoT Sensors
Explain your reasoning.
Key Takeaways
Apache Cassandra performance is largely determined by design decisions made before data is inserted.
Remember these principles:
- Model tables around queries
- Design partition keys carefully
- Use secondary indexes cautiously
- Select compaction strategies based on workload patterns
- Monitor read and write performance continuously
The best Cassandra deployments are not the ones with the most hardware—they are the ones with the best data model.
In the next Cassandra learning article, we'll explore replication, consistency levels, and cluster scalability techniques for production environments.
Text


Comments